 Carrier-Grade Routing Reliability: Evaluating Dual-Engine Redundancy in Core Routing Devices
17 Jul, 2026. Posted by:XPONSHOP
Most Views Posts
The Ultimate Guide to OLT Uplink Requirements for 10G PON: Architecture, Backplane Bandwidth, and Deployment
2026-08-28 09:50:08
Ultra-Low Latency Packet Buffering Engine Factsheet: QCT-9000 Series
2026-06-18 13:58:05
Overcoming Network Bottlenecks: Enterprise Configuration Manual for Top 10 Switch Configuration Mistakes to Avoid
2026-06-25 14:48:16
Popular Posts
Carrier-Grade Routing Reliability: Evaluating Dual-Engine Redundancy in VRRP Configuration for High-Availability Networks
2026-06-09 14:21:48
Troubleshooting ONT admin/admin: Default Login Password Not Working FAQ
2026-08-12 14:01:42
Inside the Hardware: Power Modules, Fan Trays, and Silicon Efficiency of Independent Telecom Hardware Vendors
2026-08-14 11:28:08
Random Posts
Troubleshooting ONT DNS Server Not Responding: Optical Interfaces, Stacking Errors & L3 Protocols
2026-10-30 09:49:32
High-Density Fiber Infrastructure Application Note: OEM FTTH Drop Cable Optical Attenuation per Kilometer Standard Values
2026-07-31 10:16:51
The Ultimate Guide to Saving Money on ISP Startup Costs with OEM Hardware: Architecture, Backplane Bandwidth, and Deployment
2026-08-03 10:21:24
Recent Posts
AI Optical Transceivers vs. Telecom Optical Transceivers: Two ‘Personalities’ of the Same Component
2026-10-30 11:30:33
Overcoming Network Bottlenecks: Enterprise Configuration Manual for Nintendo Switch NAT Type D Resolution
2026-10-30 10:06:06
Cisco Business 350 Series Managed Switch Physical Security and Power Efficiency - Official Technical Overview & Hardware Datasheet
2026-10-30 10:03:46
About
XponShop blog describes some basics for Huawei / ZTE /
Nokia / FiberHome GPON OLT, ONT, SFP, and Site Power...
such as configurations, issue troubleshooting, knowledge
sharing, and keeps updating.
Recent posts
 AI Optical Transceivers vs. Telecom Optical Transceivers: Two ‘Personalities’ of the Same Component
27 Mar, 2025
 Overcoming Network Bottlenecks: Enterprise Configuration Manual for Nintendo Switch NAT Type D Resolution
27 Mar, 2025
 Cisco Business 350 Series Managed Switch Physical Security and Power Efficiency - Official Technical Overview & Hardware Datasheet
27 Mar, 2025
AI Optical Transceivers vs. Telecom Optical Transceivers: Two ‘Personalities’ of the Same Component
27 Mar, 2025
Overcoming Network Bottlenecks: Enterprise Configuration Manual for Nintendo Switch NAT Type D Resolution
27 Mar, 2025
Cisco Business 350 Series Managed Switch Physical Security and Power Efficiency - Official Technical Overview & Hardware Datasheet
27 Mar, 2025
Products from the blog
Introduction
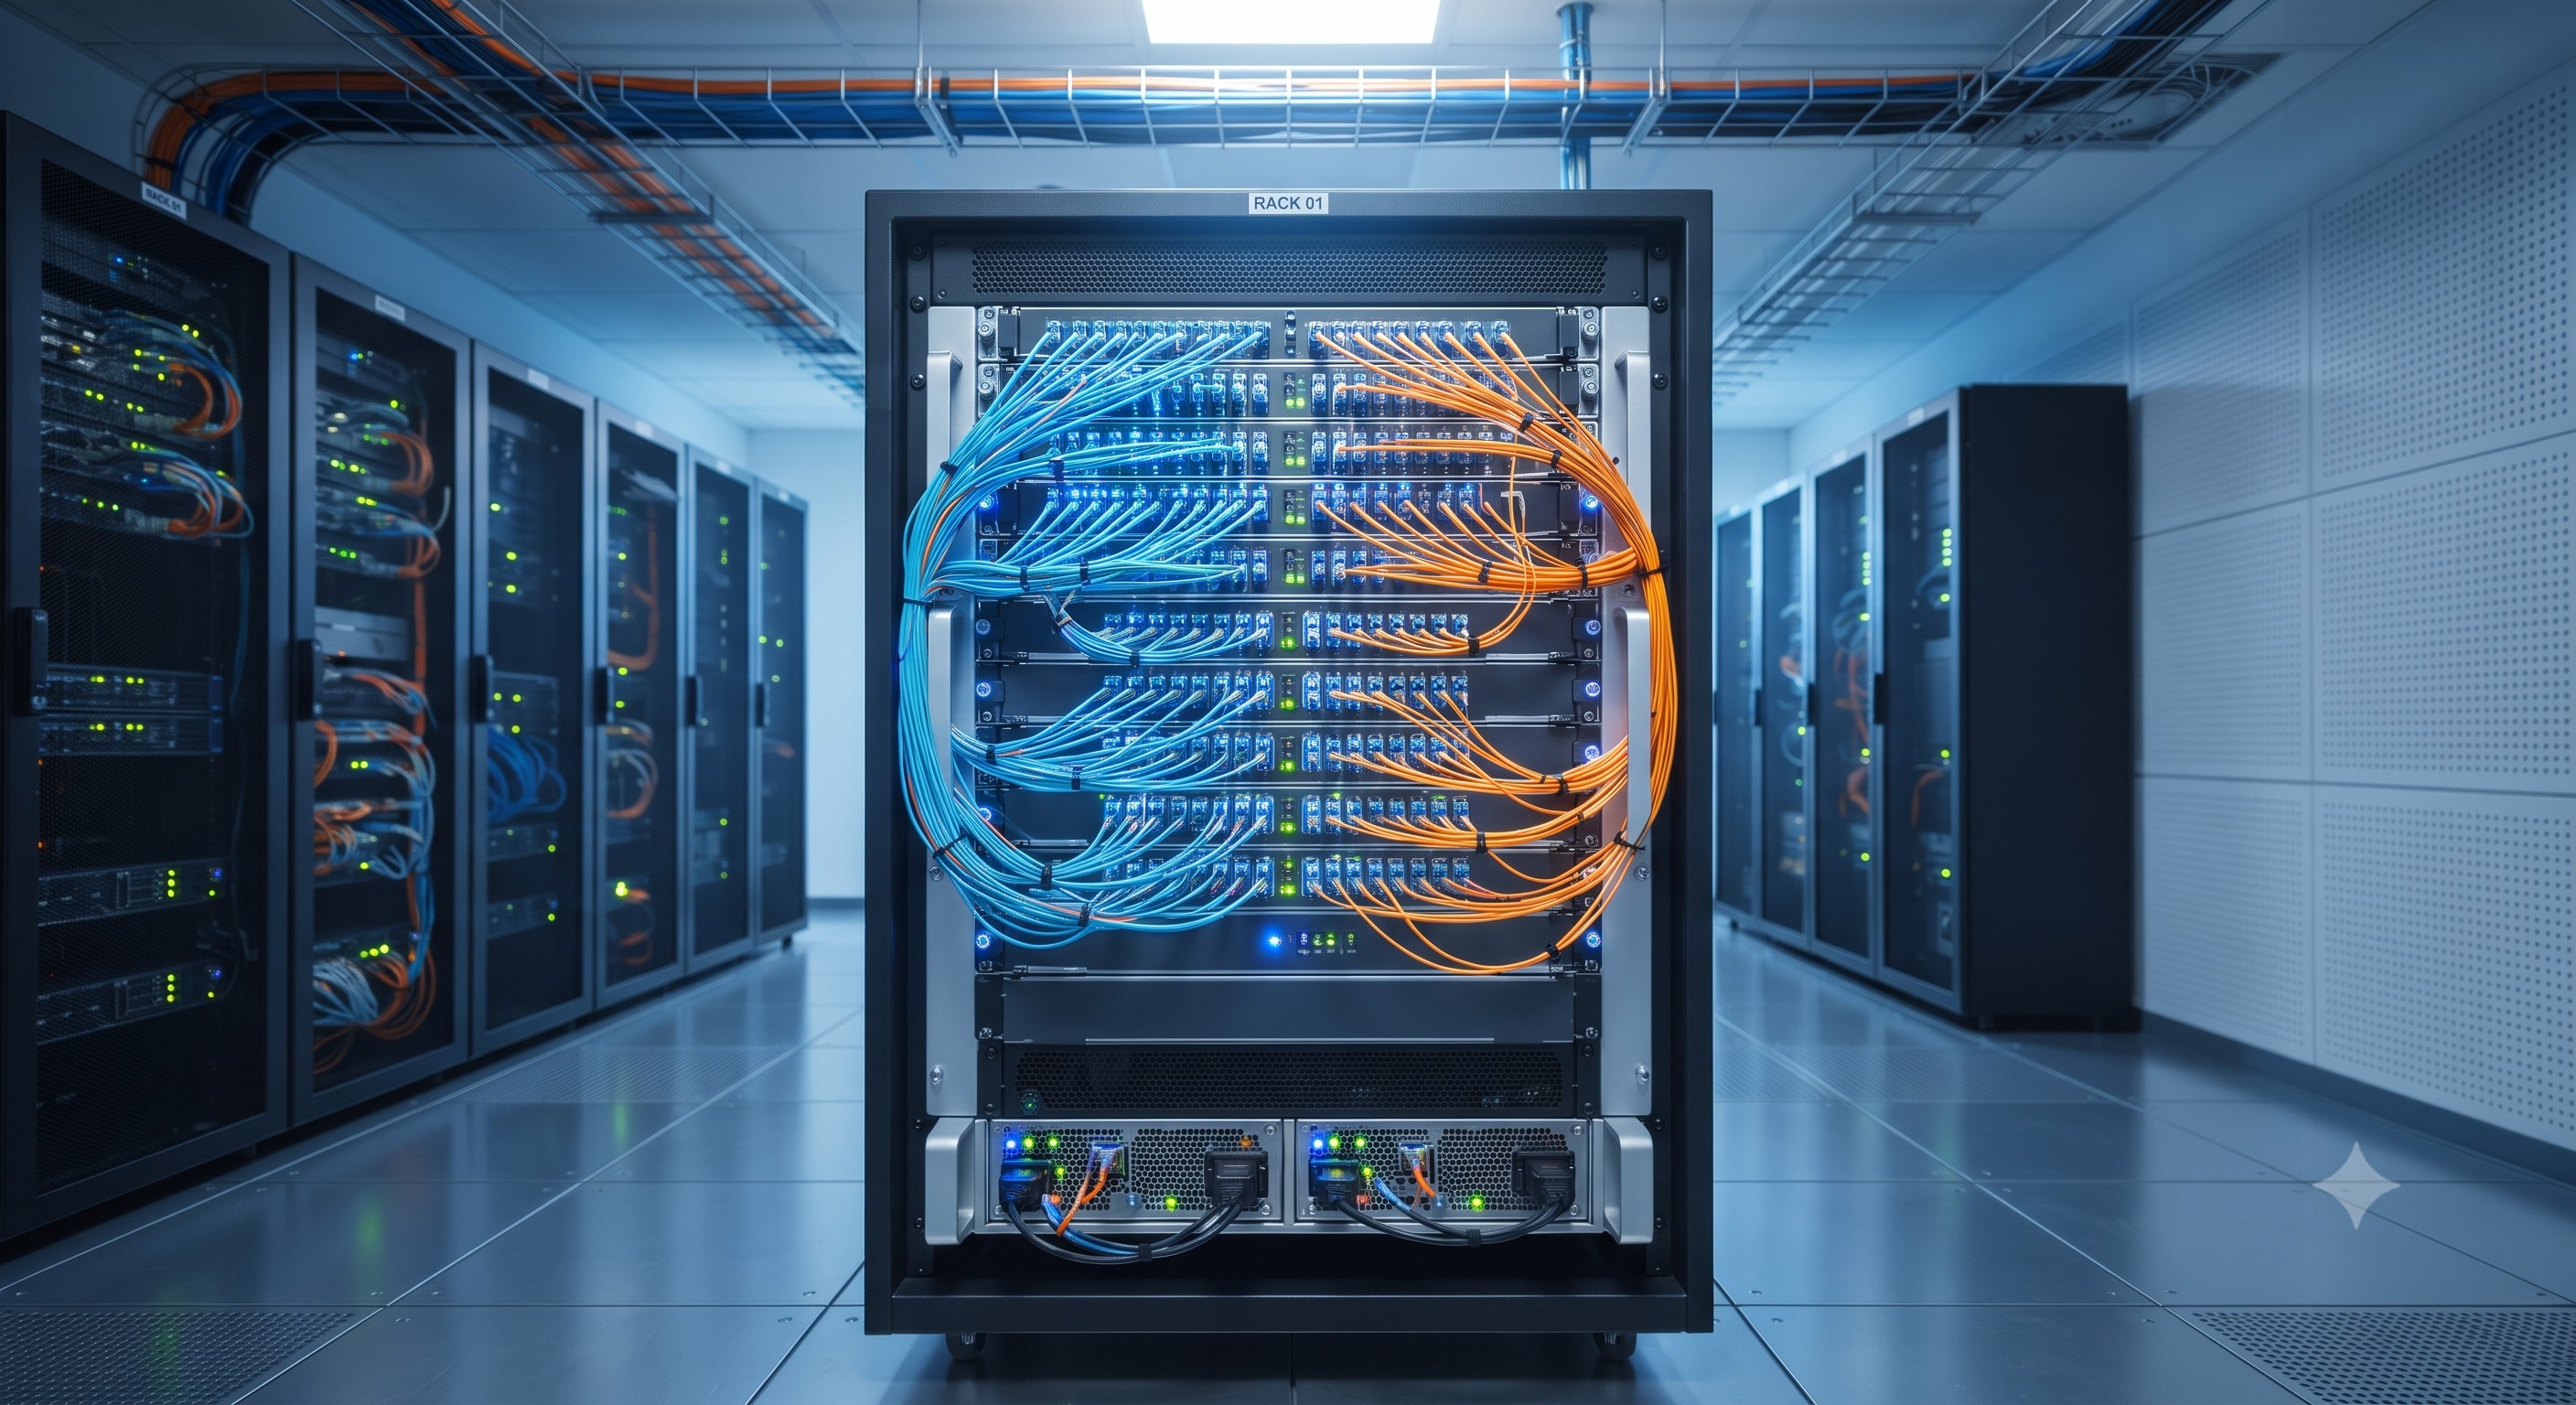
In the modern enterprise and service provider landscape, the core routing device is no longer just a high-speed forwarding engine; it is the central nervous system of the entire digital ecosystem. The shift from traditional, geographically distributed router clusters to consolidated, high-capacity monolithic systems has introduced immense economic benefits but has also centralized the risk of catastrophic network failure . This architectural evolution makes the implementation of robust redundancy in core routing devices not merely a best practice, but an absolute prerequisite for achieving carrier-grade reliability. As bandwidth demands surge past 400G and 800G boundaries, the margin for error shrinks to zero, making the evaluation of dual-engine redundancy a critical task for any network architect responsible for mission-critical infrastructure. This technical deep-dive provides a quantitative analysis of redundancy mechanisms, from N+1 fabric redundancy to stateful failover, mapping them against real-world SLA requirements and industry benchmarks.
Core Architecture: Beyond Single Points of Failure
The High-Availability Imperative
Commercial Internet architectures are increasingly driven by the need to improve capital unit costs, often leading to the deployment of larger, more powerful routers in non-redundant configurations. While this reduces interconnect costs by utilizing a high-speed switching fabric internally rather than revenue-producing interfaces, it fundamentally violates the traditional Internet architectural principle of building reliable systems from semi-reliable, redundant elements . The solution lies in implementing sophisticated High Availability (HA) and Non-Stop operations at the system level. A truly carrier-grade core routing device must be engineered to withstand multiple hardware and software failures without impacting data or control plane operations.
N-Modular Redundancy for Control Plane
To address the reliability challenges of large-scale core routers, advanced architectures employ N-Modular Redundancy for control process software. This approach leverages an eventually consistent framework, often built on a distributed database, to ensure that the system can continue processing both control and data messages even after multiple failures . This is a significant step beyond simple 1+1 processor pairs, offering a path towards truly non-stop routing.
Redundancy Mechanisms: Dual-Engine and Fabric Design
Control Plane Redundancy
The core of any resilient routing platform is its control plane. Leading platforms, such as the Juniper MX960, feature dedicated hardware like the RE-S-1800X4 Routing Engines . In a typical dual-engine configuration, one Routing Engine functions as the master, with full control over the chassis and routing tables, while the other acts as a standby, ready to take over instantly . Failover can be triggered by hardware failures, kernel crashes, or even the failure of specific software processes, with the backup engine assuming mastership often automatically .
Modern implementations provide different levels of switchover granularity. A basic failover involves resetting the switch plane and reinitializing the Packet Forwarding Engine, which interrupts traffic. However, Graceful Routing Engine Switchover (GRES) preserves interface and kernel information, while Nonstop Active Routing (NSR) maintains routing protocol information, enabling hitless failover with no traffic interruption . The Juniper MX2010, for example, takes this further with N+1 fabric redundancy and even N+N power feed redundancy, managing two routers as a single element via Virtual Chassis technology .
Data Plane and Forwarding Redundancy
Forwarding performance and reliability are deeply intertwined. Redundancy in the data plane is often realized through N+1 fabric modules, ensuring that the loss of a single fabric component does not degrade switching capacity. The strategic placement of TCAM (Ternary Content-Addressable Memory) for lookups is also crucial. For instance, the failure rate of PBR-specific ASIC logic is remarkably low at 3.2 FIT, but without dual banks, a TCAM parity error or table fragmentation can lead to service-affecting outages . Hardware-based Stateful Switchover (SSO) ensures that the backup engine has a synchronized copy of the forwarding table, adjacency table, and policy state.
Technical Specifications
To quantify the reliability of these systems, we must look beyond simple bandwidth numbers. The following table provides a high-level comparison of component reliability and redundancy schemes. Note that these figures are based on normalized data from Tier-1 vendor reliability reports and Telcordia SR-332 calculations .
Deployment Scenarios and Best Practices
ISP and Multi-Homing Architectures
For ISPs, redundant core appliances are fundamental to maintaining service availability. A typical deployment involves two core appliances, each connected to peering ISPs and downstream customers. This architecture ensures that maintenance on one appliance does not cause service interruption and that a single hardware failure does not isolate the network .
Addressing Shunt Traffic in Redundant BNG Setups
Advanced redundancy scenarios, such as Multi-Chassis Link Aggregation (MC-LAG) in Broadband Network Gateway (BNG) environments, introduce complex challenges like shunt traffic. In a dual BNG setup, downstream traffic destined for a subscriber may arrive at the standby BNG, which must then forward it to the active BNG across a redundant interface. This can cause substantial load on inter-chassis links. Optimizing this requires mechanisms like SRRP fate-sharing and SRRP-aware routing to advertise more granular routes to the core, directing traffic to the active BNG and eliminating the shunt traffic overhead .
Conclusion
The data is irrefutable: for any network promising carrier-grade reliability (99.999% uptime), the implementation of comprehensive redundancy in core routing devices is non-negotiable. The move towards centralized, high-capacity routing systems necessitates a shift from relying on external router redundancy to building internal resilience into the system architecture. From dual control plane engines and N+1 fabric modules to sophisticated software mechanisms like NSR and SSO, the modern core router must be a marvel of engineering designed to outlast component failures. As the industry moves towards 800G and 1.6T interfaces, the internal ASIC pipeline and failover mechanisms will become even more critical. Network architects must prioritize platforms with demonstrable MTBF figures exceeding 1 million hours for redundant subsystems, stateful failover capabilities, and compliance with benchmarks like ITU-T G.8032 to ensure their core network remains the bedrock of their digital services, not a liability .