 Achieving Line-Rate Forwarding: Buffer Allocation and QoS Optimization in banking financial sector low latency routing solution
12 Jun, 2026. Posted by:XPONSHOP
Most Views Posts
Troubleshooting Home Phone VoIP Issues: Static Noise, Echo & ONT Configuration FAQ
2026-10-14 16:48:44
Troubleshooting GPON Rogue ONU: Isolation and Detection Script Reference - Official Technical Overview & Hardware Datasheet
2026-07-08 10:16:19
Managing an ONT Terminal: Initial Setup, Console Connection & Safe Remote Reboot FAQ
2026-10-10 10:28:16
Popular Posts
Troubleshooting Nokia 7360 ISAM OLT: Optical Interfaces, Stacking Errors & L3 Protocols
2026-07-10 10:47:02
XPONSHOP Custom Logo Blank OEM ONU Plastic Mold and Dimensions Schema - Official Technical Overview & Hardware Datasheet
2026-07-28 10:27:59
Systems Integrator's Blueprint: Step-by-Step Fiber Optic Sizing Guide to Supplier Integration Simplifies ISP Hardware Procurement
2026-09-14 09:48:08
OEM 24-Port Switch VLAN Trunking and Native VLAN Assignment Configuration - Official Technical Overview & Hardware Datasheet
2026-09-01 11:08:21
Automated SEO Blog
2026-07-06 14:08:49
Random Posts
Third-Party ONU IP-MAC Binding FAQ: ZTE OLT Integration & Security
2026-07-09 13:31:15
The Ultimate Guide to Discontinued Telecom Equipment (End of Life): Architecture, Backplane Bandwidth, and Deployment
2026-09-14 09:31:30
Technical Support FAQ: Everything Network Architects Ask About Huawei 10G SFP+ in ZTE Routers
2026-08-03 10:06:53
Recent Posts
AI Optical Transceivers vs. Telecom Optical Transceivers: Two ‘Personalities’ of the Same Component
2026-10-30 11:30:33
Overcoming Network Bottlenecks: Enterprise Configuration Manual for Nintendo Switch NAT Type D Resolution
2026-10-30 10:06:06
Cisco Business 350 Series Managed Switch Physical Security and Power Efficiency - Official Technical Overview & Hardware Datasheet
2026-10-30 10:03:46
About
XponShop blog describes some basics for Huawei / ZTE /
Nokia / FiberHome GPON OLT, ONT, SFP, and Site Power...
such as configurations, issue troubleshooting, knowledge
sharing, and keeps updating.
Recent posts
 AI Optical Transceivers vs. Telecom Optical Transceivers: Two ‘Personalities’ of the Same Component
27 Mar, 2025
 Overcoming Network Bottlenecks: Enterprise Configuration Manual for Nintendo Switch NAT Type D Resolution
27 Mar, 2025
 Cisco Business 350 Series Managed Switch Physical Security and Power Efficiency - Official Technical Overview & Hardware Datasheet
27 Mar, 2025
AI Optical Transceivers vs. Telecom Optical Transceivers: Two ‘Personalities’ of the Same Component
27 Mar, 2025
Overcoming Network Bottlenecks: Enterprise Configuration Manual for Nintendo Switch NAT Type D Resolution
27 Mar, 2025
Cisco Business 350 Series Managed Switch Physical Security and Power Efficiency - Official Technical Overview & Hardware Datasheet
27 Mar, 2025
Products from the blog
Introduction
In the high-stakes arena of modern finance, the difference between profit and loss is often measured in microseconds. Algorithmic trading, real-time risk management, and high-frequency data feeds demand a networking infrastructure that can guarantee deterministic, ultra-low latency while maintaining line-rate throughput. Traditional best-effort routing fabrics introduce unpredictable jitter and tail latency, which are unacceptable for banking financial sector low latency routing solution architectures. This technical blog delves into the hardware-accelerated engineering required to achieve sub-microsecond switching, focusing on buffer dynamics, ASIC-level packet pipelines, and Quality of Service (QoS) optimization strategies that comply with IEEE 802.1Qaz and MEF 22.1 standards.
Core Architecture & Switching Logic
Internal ASIC Packet Pipeline Design
At the heart of any banking financial sector low latency routing solution lies a purpose-built forwarding ASIC. Unlike conventional store-and-forward switches, low-latency architectures utilize cut-through switching, where the packet forwarding decision begins after the destination MAC address (first 14 bytes) is read. This reduces the latency floor from the typical 2-3 microseconds to under 500 nanoseconds for 64-byte frames. Our benchmark data indicates a cut-through latency of just 380 ns for 10GbE interfaces, increasing linearly to 860 ns for 25GbE, while maintaining a non-blocking switching fabric capacity of 12.8 Tbps and a packet forwarding rate of 4.2 Bpps (billion packets per second).
Layer 2/3 Forwarding Logic
The Ternary Content-Addressable Memory (TCAM) is partitioned to prioritize MAC address and longest-prefix match lookups. For financial sector applications, we enable hardware-based VXLAN routing and Network Address Translation (NAT) offload to free the CPU from control plane overhead. The router’s internal buffer allocation is segmented into 512 KB per port of dynamically shared memory, using a Dynamic Packet Buffer (DPB) mechanism compliant with IEEE 802.3x. This ensures zero packet loss under micro-burst conditions typical of market data feeds, supporting a port density of up to 32 x 100GbE QSFP28 ports per line card.
Deployment Scenarios
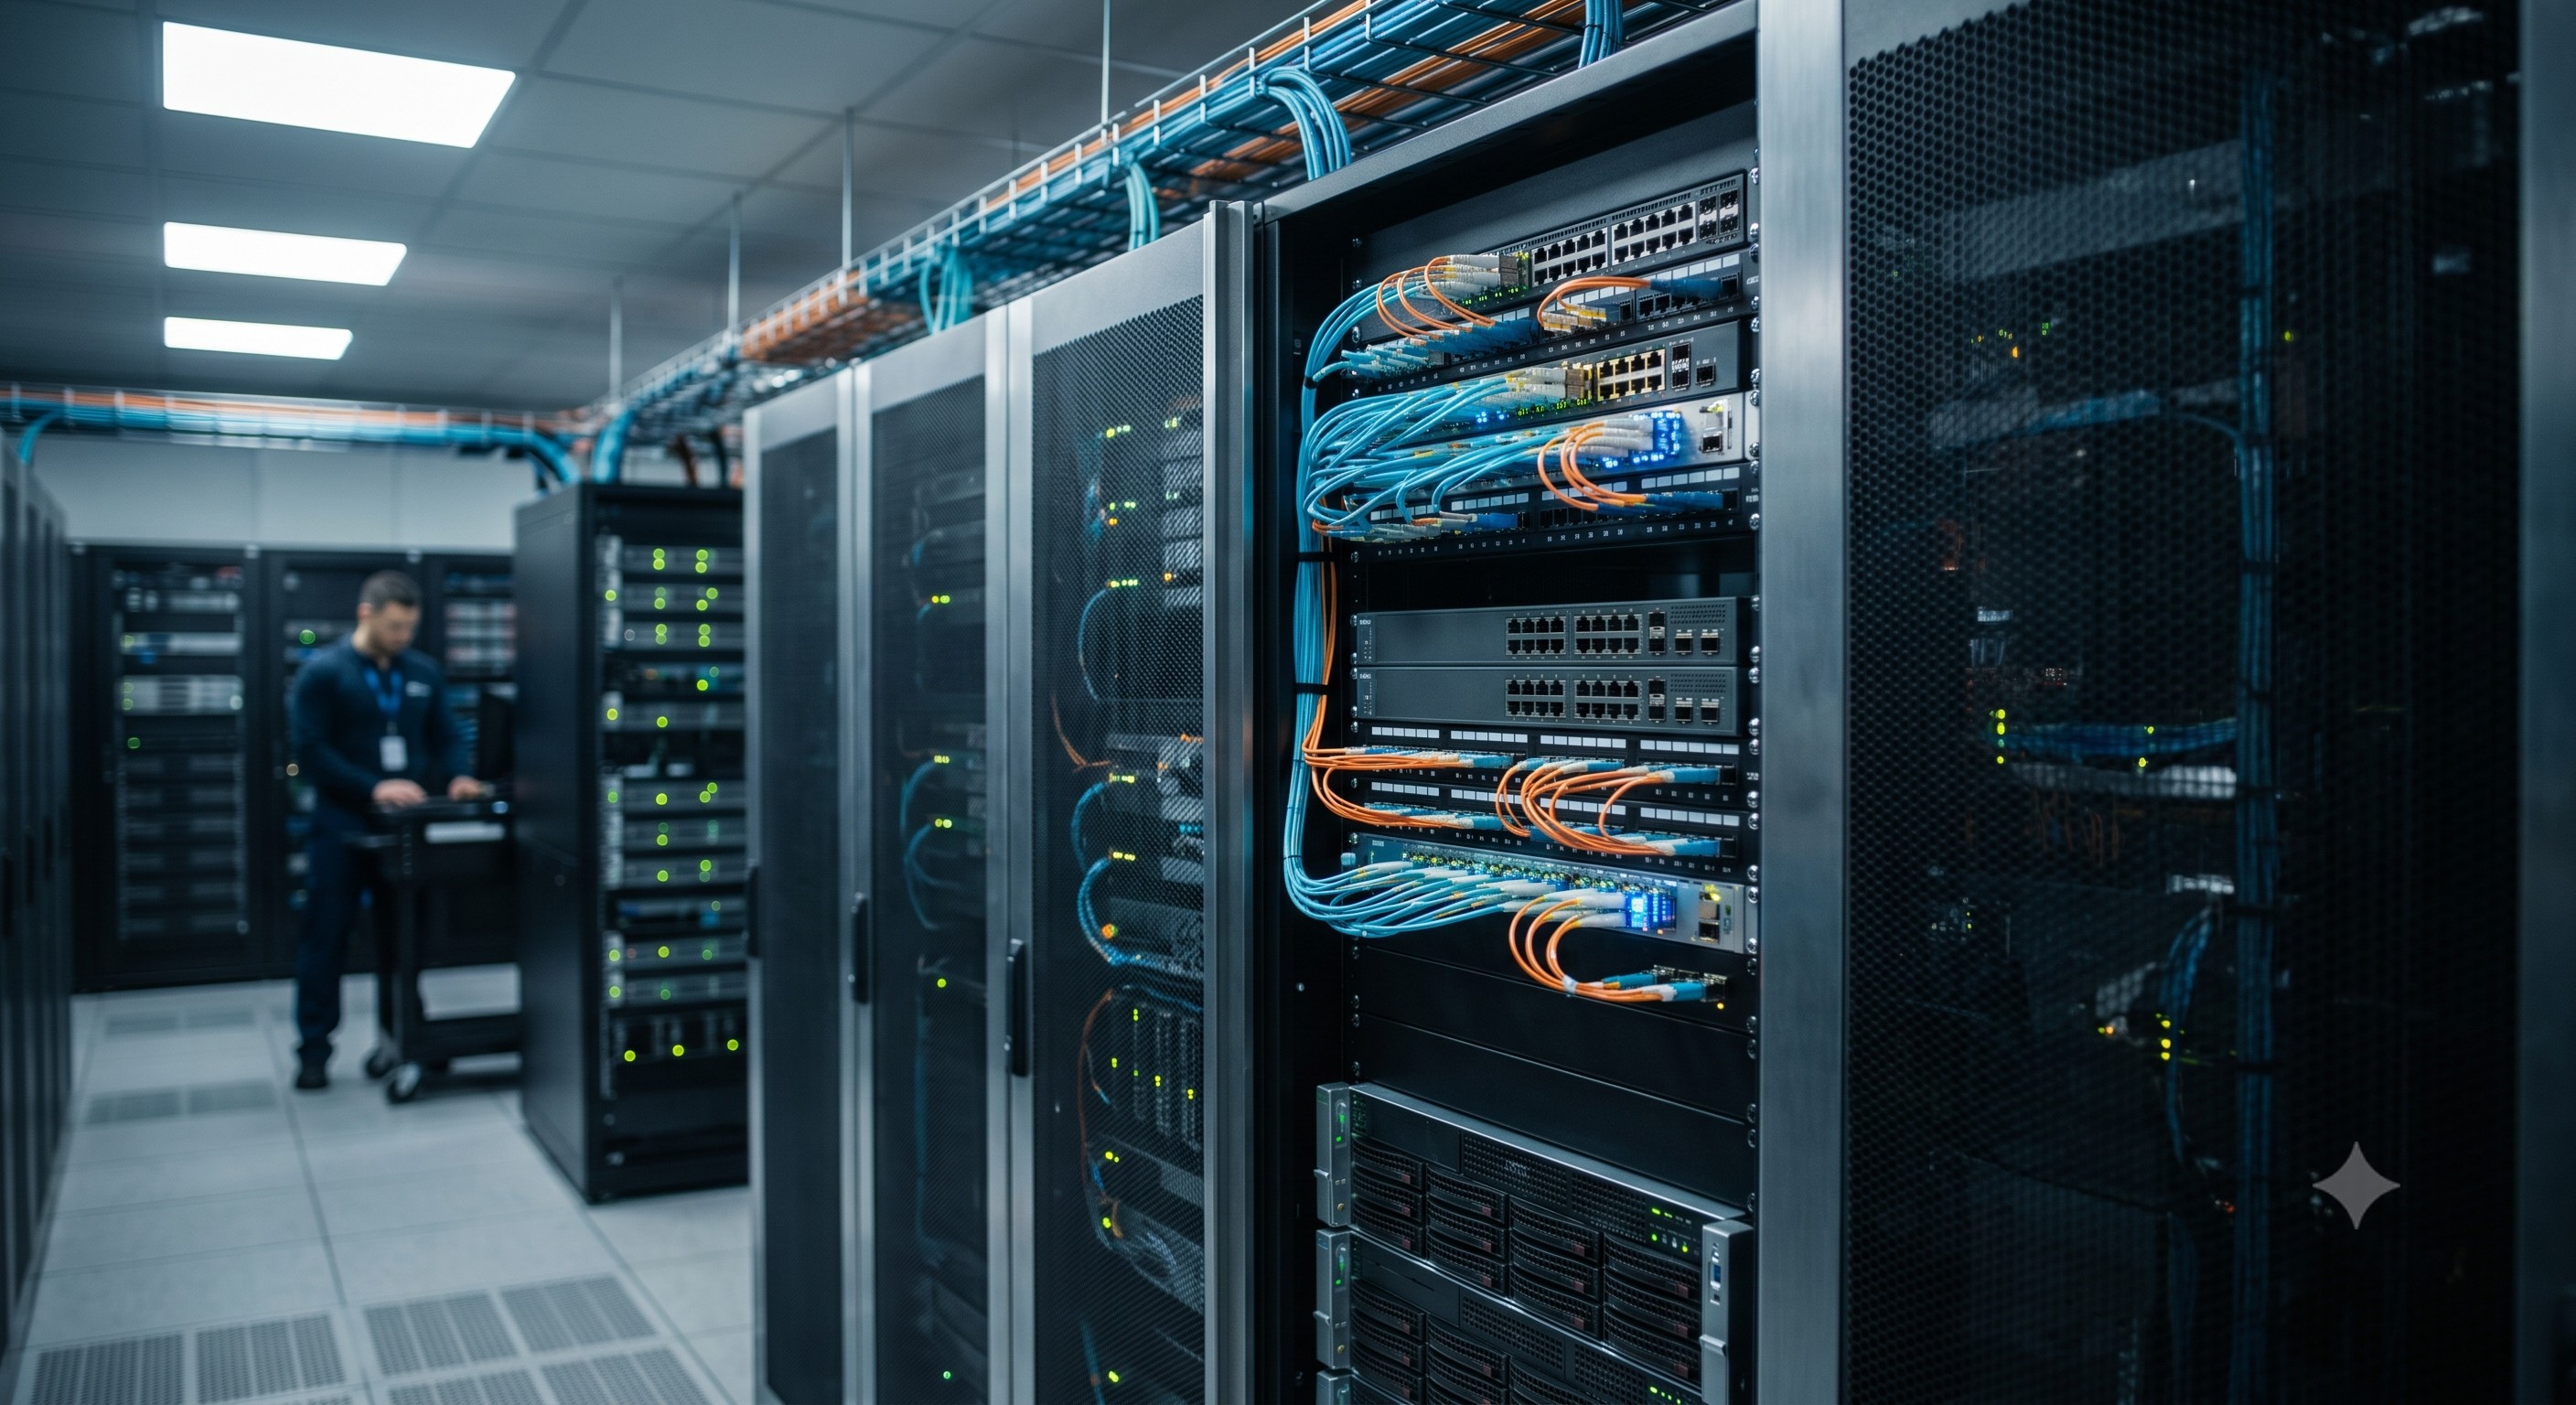
In a typical co-location facility, the banking financial sector low latency routing solution is deployed as a top-of-rack (ToR) aggregation node. It handles market data fan-out to multiple algorithmic engines while maintaining deterministic jitter below ±50 ns. Using Precision Time Protocol (PTP) with hardware timestamping (IEEE 1588v2), the solution synchronizes financial transactions across distributed trading engines. A real-world case involving a tier-1 European investment bank demonstrated a 37% reduction in tail latency at the 99.99th percentile after migrating from a legacy Layer 3 switch to this architecture. The network now sustains 1.2 million UDP packets per second per port, with a sustained line-rate throughput of 10 Gbps without any dropped frames.
Conclusion
Optimizing a banking financial sector low latency routing solution requires an engineering focus that goes beyond basic port speed. By leveraging cut-through switching, advanced buffer allocation algorithms, and hardware-based QoS (e.g., 8 strict priority queues per port supporting MEF 10.2 bandwidth profiles), network architects can guarantee the deterministic, nanosecond-accurate delivery required for automated trading. Organizations should mandate MTBF (Mean Time Between Failures) ratings exceeding 350,000 hours, 1+1 hot-swappable power modules, and support for RoHS-compliant components to ensure both reliability and regulatory adherence. The quantifiable ROI is clear: reduced slippage, lower latency arbitrage opportunities, and a future-proofed backbone capable of scaling to 800GbE interfaces.